Synthetic Data: Its Value for Better AI Models
Data naturally plays a crucial role in companies undergoing digital transformation. But as the demand for high-quality data in large quantities grows, we often encounter challenges such as privacy restrictions and a lack of sufficient data for specialized tasks. This is where the concept of synthetic data emerges as a groundbreaking solution.
Why Synthetic Data?
- Privacy and Security: In sectors where privacy is a major concern, such as healthcare or finance, additional data provides a way to protect sensitive information. Because the data does not come directly from individual people, the risk of privacy breaches is significantly reduced.
- Availability and Diversity: Specific datasets, particularly in niche areas, may be scarce. Synthetic data can fill these gaps by generating data that would otherwise be difficult to obtain.
- Training and Validation: In the world of AI and machine learning, large amounts of data are needed to train models effectively. Synthetic data can be used to expand training datasets and improve the performance of these models.
Applications
- Healthcare: By creating synthetic patient records, researchers can study disease patterns without using real patient data, thereby safeguarding privacy.
- Autonomous Vehicles: Large amounts of traffic data are needed to test and train self-driving cars. Synthetic data can generate realistic traffic scenarios that help improve the safety and efficiency of these vehicles.
- Financial Modeling: In the financial sector, synthetic data can be used to simulate market trends and conduct risk analyses without revealing sensitive financial information.
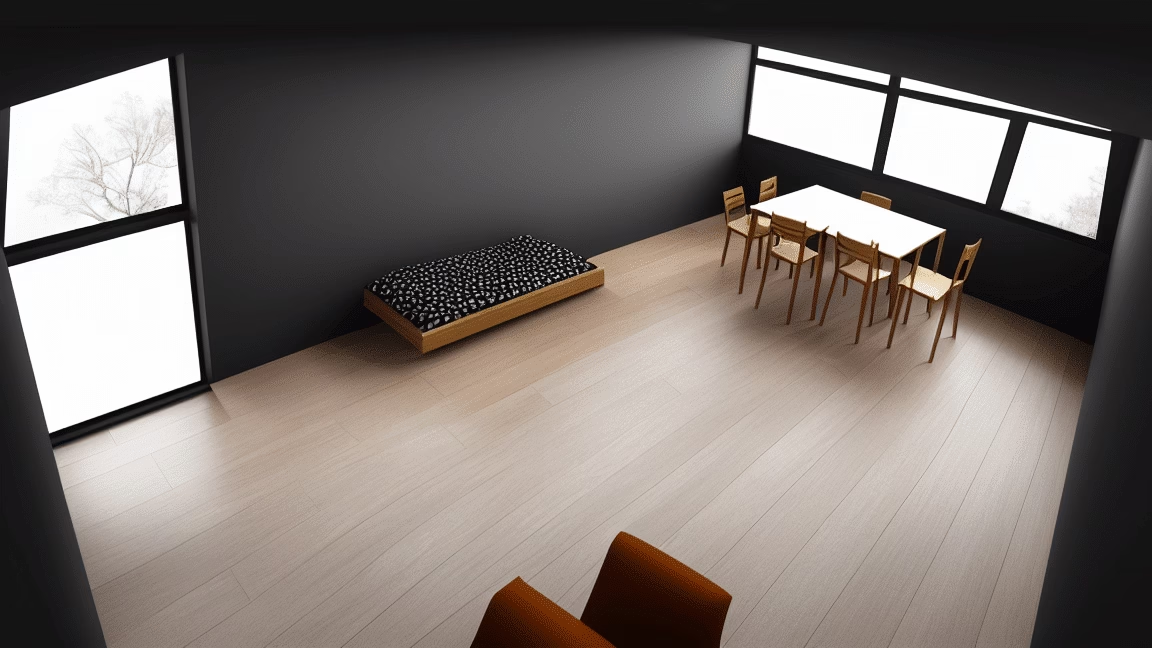
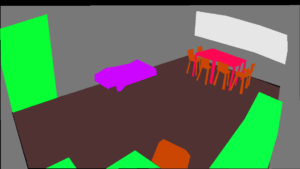
Example: A synthetically generated room
Challenges and Considerations
Although it offers many benefits, it also presents challenges. Ensuring the quality and accuracy of this data is crucial. Inaccurate synthetic datasets can lead to misleading results and decisions. It is also important to strike a balance between using synthetic data and real data in order to gain a complete and accurate picture. In addition, extra data can be used to reduce imbalances (BIAS) in a dataset. Large language models use generated data because they have simply already processed the Internet and need even more training data to improve.
Conclusion
Synthetic data is a promising development in the world of data analysis and Machine learning. It offers a solution to privacy issues and improves data availability. It is also invaluable for training advanced algorithms. As we continue to develop and integrate this technology, it is essential to safeguard the quality and integrity of the data so that we can harness the full potential of synthetic data.
Need help applying AI effectively? Make use of our consulting services


